
The DOM tree structure is how a browser represents an HTML document in memory: a tree of nodes with the document at the root, the <html> element below it, then <head> and <body>, and every element, piece of text and comment as a node under its parent. JavaScript reads and changes the page through this tree, using properties such as parentNode, children and nextElementSibling and methods such as querySelector().
This guide explains the DOM tree structure, the types of nodes in it, how to traverse and modify it, and four behaviours that regularly surprise developers. I checked every example in a real browser (Chromium, through headless Brave), and the outputs shown come from that test.
What Is the DOM?
The Document Object Model (DOM) is the programming interface browsers expose for web pages. When a browser parses HTML, it doesn’t keep the text; it builds objects for every part of the document and links them into a tree. CSS styles that tree, JavaScript reads and changes it, and the browser re-renders when it changes. HTML is the source; the DOM is the live, in-memory version.
DOM Tree Structure, Visualized
Take this small page:
<!DOCTYPE html>
<html lang="en">
<head>
  <title>Shopping list</title>
</head>
<body>
  <!-- main list -->
  <ul id="list">
    <li class="item">Milk</li>
    <li class="item">Bread</li>
    <li class="item">Eggs</li>
  </ul>
  <p>Paragraph <div>inside a paragraph?</div></p>
  <table id="t"><tr><td>cell</td></tr></table>
</body>
</html>
The browser turns the first part of it into this tree:
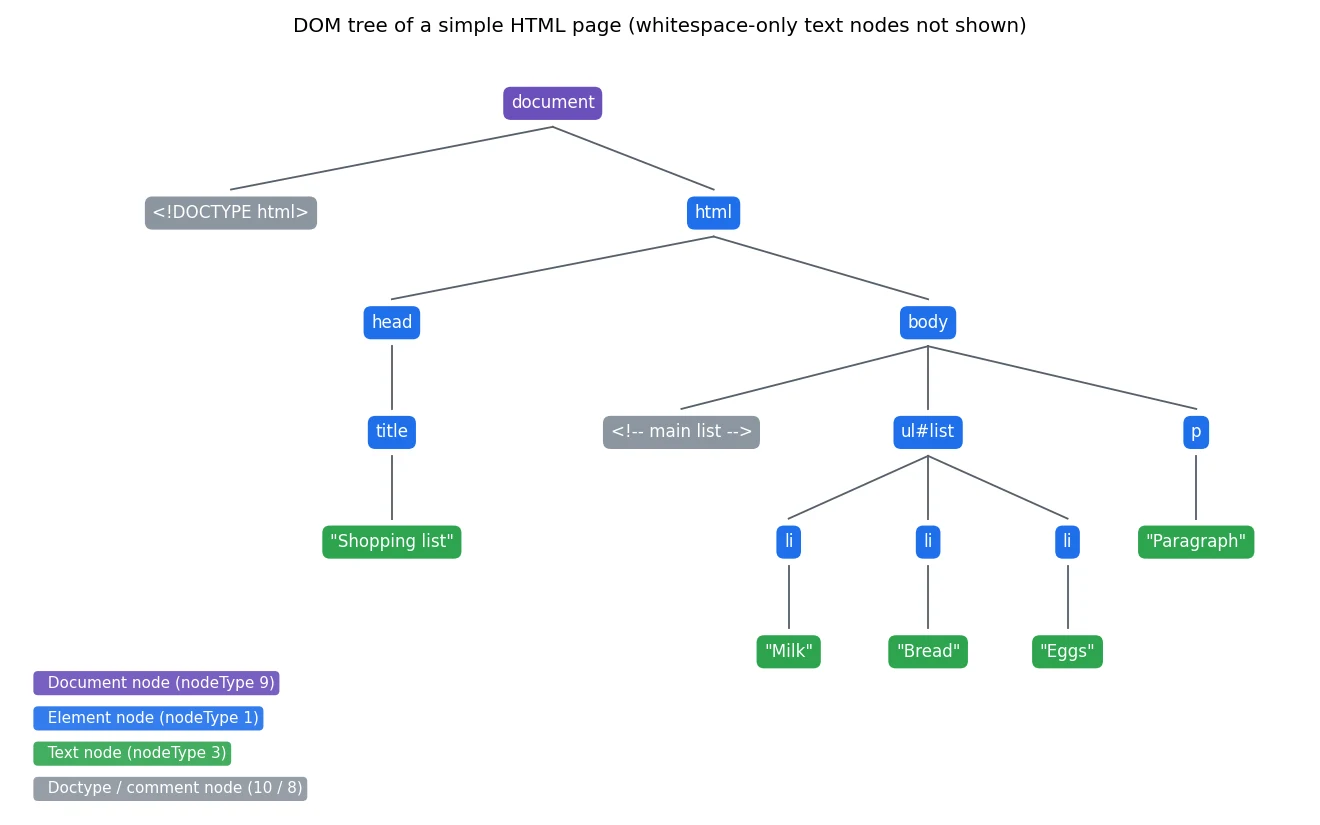
The vocabulary is borrowed from family trees:
- Root: the
documentnode, the top of the tree. - Parent and child:
<ul>is the parent of each<li>; each<li>is a child of the<ul>. - Siblings: nodes with the same parent, like the three
<li>elements. - Ancestors and descendants:
<body>is an ancestor of every<li>; the text “Milk” is a descendant of<ul>. - Leaf: a node with no children, typically a text node.
Types of Nodes in the DOM Tree
Every node has a nodeType number. Reading them from the example page returned 9, 10, 1, 3, 8 for the document, the doctype, an <li>, its text and the comment:
| Node type | nodeType | nodeName | Example |
|---|---|---|---|
| Document | 9 | #document | The document object |
| Document type | 10 | html | <!DOCTYPE html> |
| Element | 1 | Tag name in capitals, such as LI | <li class="item"> |
| Text | 3 | #text | “Milk”, and also whitespace between tags |
| Comment | 8 | #comment | <!-- main list --> |
| Document fragment | 11 | #document-fragment | A lightweight container for building nodes before inserting them |
Attributes such as class="item" are not children in the tree. They belong to their element and are read with getAttribute(), the attributes property, or properties like className and dataset.
Navigating the DOM Tree
There are two sets of navigation properties: ones that include every node, and ones that only include elements. Most of the time you want the element versions:
| All nodes (including text and comments) | Elements only |
|---|---|
parentNode | parentElement |
childNodes | children |
firstChild / lastChild | firstElementChild / lastElementChild |
nextSibling / previousSibling | nextElementSibling / previousElementSibling |
const list = document.getElementById('list');
const milk = list.firstElementChild;      // <li>Milk</li>

milk.nextElementSibling.textContent;      // "Bread"
milk.parentElement.tagName;               // "UL"
milk.closest('body').tagName;             // "BODY": nearest ancestor matching a selector
list.children.length;                     // 3
To find elements anywhere, use selectors: document.querySelector('#list .item') returns the first match and querySelectorAll('.item') returns all of them. getElementById() is the fastest way to get one element by ID.
Four DOM Behaviours That Surprise Developers
1. Whitespace becomes text nodes
The line breaks and indentation between tags are text nodes too. For the three-item list above, the browser reported:
list.childNodes.length    // 7
list.children.length      // 3
[...list.childNodes].map((n) => n.nodeName)
// ['#text', 'LI', '#text', 'LI', '#text', 'LI', '#text']

list.firstChild           // a #text node containing "\n    "
milk.nextSibling.nodeName // "#text", not the next <li>
That’s why code using firstChild or nextSibling often gets a text node when it expects an element. Use firstElementChild, nextElementSibling and children instead.
2. The DOM is not always the HTML you wrote
Browsers follow the HTML specification’s rules for fixing invalid or incomplete markup. In the example, the source has a <div> inside a <p>, which isn’t allowed, and a table without <tbody>. The body’s children came out as:
[...document.body.children].map((e) => e.tagName)
// ['UL', 'P', 'DIV', 'P', 'TABLE']

document.getElementById('t').firstElementChild.tagName
// 'TBODY'   (inserted by the parser)
The parser closed the paragraph before the <div>, then created an extra empty <p> for the stray closing tag, and inserted a <tbody>. When a selector doesn’t match what you expect, inspect the DOM in DevTools (the Elements panel shows the tree, not the source), and validate your HTML. My guide to HTML5 page structure covers valid markup.
3. Live collections change while you use them
getElementsByClassName(), getElementsByTagName() and children return live collections that update automatically; querySelectorAll() returns a static snapshot:
const live = document.getElementsByClassName('item');
const snapshot = document.querySelectorAll('.item');
// both have 3 items

list.append(Object.assign(document.createElement('li'), { className: 'item', textContent: 'Butter' }));
live.length;       // 4
snapshot.length;   // 3
Live collections cause a classic bug. Removing the class inside a loop over the live collection shrinks it while you iterate, so items get skipped:
const items = document.getElementsByClassName('item');
for (let i = 0; i < items.length; i++) {
  items[i].classList.remove('item');
}
// My test: visited 2 of 4 items; 2 still had the class

// Fix: loop over a static copy
for (const el of document.querySelectorAll('.item')) el.classList.remove('item');
4. Text and comments are part of the tree too
Comments show up in childNodes (the body’s first nodes were #text, #comment, #text), and textContent includes all descendant text. To collect only meaningful text, walk the tree with a TreeWalker:
const walker = document.createTreeWalker(document.body, NodeFilter.SHOW_TEXT, {
  acceptNode: (n) => (n.textContent.trim() ? NodeFilter.FILTER_ACCEPT : NodeFilter.FILTER_SKIP),
});
const texts = [];
while (walker.nextNode()) texts.push(walker.currentNode.textContent.trim());
// ['Milk', 'Bread', 'Eggs', 'Butter', 'Paragraph', 'inside a paragraph?', 'cell']
Modifying the DOM Tree
// Create and insert
const li = document.createElement('li');
li.textContent = 'Coffee';           // safe: text is escaped
li.dataset.new = 'true';             // sets data-new="true"
list.prepend(li);                    // <li data-new="true">Coffee</li> becomes the first item

// Other insertion methods
list.append(node);                   // last child
milk.before(node);                   // before a sibling
milk.after(node);                    // after a sibling
milk.replaceWith(node);              // replace

// Remove
milk.remove();

// Many nodes at once, with one insertion
const fragment = document.createDocumentFragment();
['Tea', 'Sugar'].forEach((t) => fragment.append(Object.assign(document.createElement('li'), { textContent: t })));
list.append(fragment);
Prefer textContent over innerHTML for text from users, because innerHTML parses its input as HTML and can run injected scripts. Batch changes where you can: every insertion can trigger style and layout work, and very large DOM trees slow pages down (see how to optimize DOM size).
The DOM in Frameworks and Other Languages
- React, Vue and others don’t stop the browser from using the DOM; they compute the changes and apply them for you. React compares its virtual tree with the previous one and updates only the DOM nodes that changed.
- Server-side code can build the same tree structure from HTML: in PHP with
DOMDocumentorDom\HTMLDocument(see how to parse HTML in PHP), in Node.js with jsdom, and in Python with Beautiful Soup. - Rendering: the browser combines the DOM with the CSS object model to decide what to draw; I explain that pipeline in how the browser rendering engine works.
Conclusion
The DOM tree is the browser’s live model of your page: a root document, elements nested as parents and children, and text and comments as nodes of their own. Navigate it with the element-only properties to avoid whitespace text nodes, remember that the parser may restructure invalid HTML, loop over static querySelectorAll results when you modify elements, and change it with createElement, append and textContent. With that model in your head, everything from debugging selectors to understanding frameworks becomes easier.
FAQs
What is the DOM tree?
The tree of nodes a browser builds from an HTML document. The document node is the root, the html element is below it, and every element, text and comment is a node under its parent. JavaScript uses it to read and change the page.
What is the difference between HTML and the DOM?
HTML is the text the server sends. The DOM is the live object tree the browser builds from it, which JavaScript can change. The DOM can differ from the HTML because the parser fixes invalid markup and scripts modify it.
What are the types of nodes in the DOM?
The main ones are the document (nodeType 9), element (1), text (3), comment (8), doctype (10) and document fragment (11) nodes.
What is the difference between childNodes and children?
childNodes includes every child node, including whitespace text nodes and comments. children includes only element nodes. In my test, a three-item list had 7 childNodes but 3 children.
Why does nextSibling return a text node?
The whitespace between tags is a text node, so the next sibling of an element is often that whitespace. Use nextElementSibling to get the next element.
What is the difference between querySelectorAll and getElementsByClassName?
querySelectorAll returns a static NodeList that doesn’t change. getElementsByClassName returns a live HTMLCollection that updates as the document changes, which can cause items to be skipped if you modify them while looping.
Is the virtual DOM the same as the DOM tree?
No. The virtual DOM is a lightweight JavaScript copy that libraries like React use to work out what changed. React then updates the real DOM tree, which is what the browser renders.







