
Web scraping with Selenium means controlling a real browser from code: Selenium opens the page, waits for JavaScript to render the content, clicks buttons or scrolls like a user, and then reads the elements you need. Install it with pip install selenium, start a browser with webdriver.Chrome() (Selenium Manager downloads the right driver automatically), wait for elements with WebDriverWait, and extract text with find_elements(By.CSS_SELECTOR, ...).
This guide builds scrapers for the most common situations: a JavaScript-rendered page, pagination, infinite scroll, and combining Selenium with BeautifulSoup, and explains when you don’t need Selenium at all. I ran every script with Selenium 4.51 and Python 3.13 against toscrape.com, a pair of sandbox sites built for practising scraping, and the outputs shown are real.
How Web Scraping Works
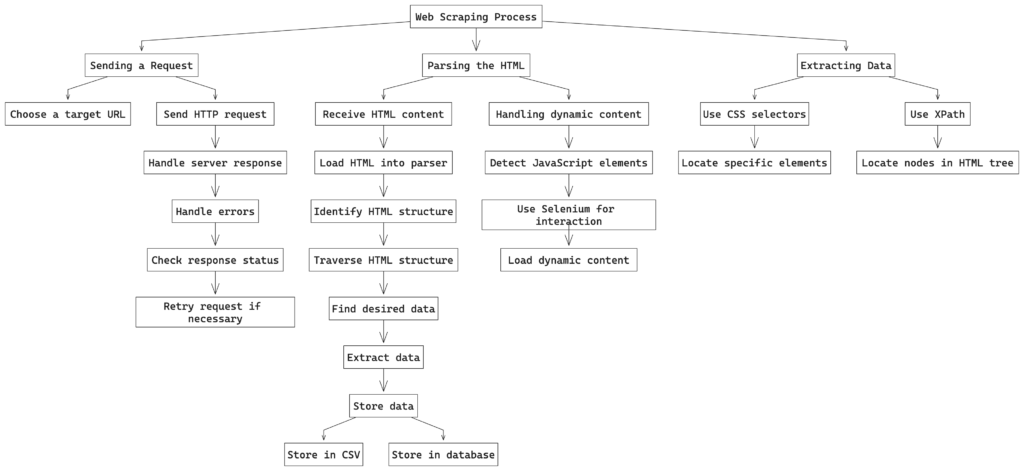
- Get the page: download the HTML with an HTTP request, or load it in a browser when the content is built by JavaScript. (New to HTTP? See what an HTTP request is.)
- Parse it: turn the HTML into a tree you can search (see HTML parsing and the DOM tree).
- Extract and store: select elements with CSS selectors or XPath, read their text or attributes, and save the results to CSV, JSON or a database.
When Do You Need Selenium?
Selenium is slower and heavier than a plain HTTP request, so first check whether you need it. The quotes site has a version that builds its content with JavaScript:
import requests
from bs4 import BeautifulSoup

# The /js/ version of the site builds its quotes with JavaScript in the browser
html = requests.get("https://quotes.toscrape.com/js/", timeout=10).text
soup = BeautifulSoup(html, "html.parser")
print("Quotes found with requests + BeautifulSoup:", len(soup.select(".quote")))
Quotes found with requests + BeautifulSoup: 0The HTML that requests downloads has no quotes in it; they’re added by a script after the page loads. A browser automation tool sees the page the way a user does. Rule of thumb: open the page with JavaScript disabled (Command Menu → “Disable JavaScript” in Chrome DevTools) or look at View Source. If the data is there, use requests and BeautifulSoup; if not, use Selenium or Playwright, or check the Network panel for the JSON API the page calls, which is often the easiest thing to scrape.
| Tool | Runs JavaScript | Speed | Best for |
|---|---|---|---|
requests + BeautifulSoup | No | Fast | Static HTML pages |
| Scrapy | No (plugins can add a browser) | Fast, built for crawling many pages | Large crawls of static sites |
| Selenium | Yes, real browser | Slower | JavaScript-heavy pages, clicking and forms; supports Chrome, Firefox, Edge and Safari and several languages |
| Playwright | Yes, real browser | Slower than HTTP, usually faster to write than Selenium | Modern sites, auto-waiting, Python or Node.js |
Setting Up Selenium
python -m venv venv
source venv/bin/activate        # Windows: venv\Scripts\activate
pip install selenium beautifulsoup4 requests
You no longer need webdriver-manager or a manually downloaded ChromeDriver. Since Selenium 4.6, the built-in Selenium Manager finds a matching driver, and downloads Chrome for Testing if no Chrome is installed. On my machine, which has no Google Chrome, the first run took about 40 seconds while it downloaded Chrome 156; later runs started in a couple of seconds.
Your First Selenium Scraper
from selenium import webdriver
from selenium.webdriver.common.by import By
from selenium.webdriver.support.ui import WebDriverWait
from selenium.webdriver.support import expected_conditions as EC

options = webdriver.ChromeOptions()
options.add_argument("--headless=new")        # no visible window
options.add_argument("--window-size=1280,900")

driver = webdriver.Chrome(options=options)    # Selenium Manager finds or downloads the driver
try:
    driver.get("https://quotes.toscrape.com/js/")

    # Wait until JavaScript has rendered at least one quote (max 10 seconds)
    WebDriverWait(driver, 10).until(
        EC.presence_of_element_located((By.CSS_SELECTOR, ".quote"))
    )

    quotes = driver.find_elements(By.CSS_SELECTOR, ".quote")
    print("Quotes found with Selenium:", len(quotes))
    for quote in quotes[:3]:
        text = quote.find_element(By.CSS_SELECTOR, ".text").text
        author = quote.find_element(By.CSS_SELECTOR, ".author").text
        tags = [t.text for t in quote.find_elements(By.CSS_SELECTOR, ".tag")]
        print(f"- {author}: {text[:60]}... {tags}")
    print("Browser:", driver.capabilities["browserName"], driver.capabilities["browserVersion"])
finally:
    driver.quit()
Quotes found with Selenium: 10
- Albert Einstein: “The world as we have created it is a process of our thinkin... ['change', 'deep-thoughts', 'thinking', 'world']
- J.K. Rowling: “It is our choices, Harry, that show what we truly are, far ... ['abilities', 'choices']
- Albert Einstein: “There are only two ways to live your life. One is as though... ['inspirational', 'life', 'live', 'miracle', 'miracles']
Browser: chrome 156.0.8078.73Key points:
--headless=newruns Chrome without a window; remove it while developing so you can watch what happens.WebDriverWaitwith expected conditions waits only as long as needed. Avoid fixedtime.sleep()calls for waiting on content: they’re either too short (flaky) or too long (slow).find_elementreturns the first match and raisesNoSuchElementExceptionif there is none;find_elementsreturns a list, which may be empty.- Locators:
By.CSS_SELECTORcovers most needs;By.XPATHhelps when you must match text (for example//a[text()="Next"]). The oldfind_element_by_*methods were removed in Selenium 4. driver.quit()infinallycloses the browser even if the script fails.
Scraping Multiple Pages (Pagination)
import csv
import time
from selenium import webdriver
from selenium.webdriver.common.by import By
from selenium.webdriver.support.ui import WebDriverWait
from selenium.webdriver.support import expected_conditions as EC
from selenium.common.exceptions import NoSuchElementException

options = webdriver.ChromeOptions()
options.add_argument("--headless=new")
driver = webdriver.Chrome(options=options)
wait = WebDriverWait(driver, 10)

rows = []
try:
    driver.get("https://quotes.toscrape.com/js/")
    page = 1
    while True:
        wait.until(EC.presence_of_element_located((By.CSS_SELECTOR, ".quote")))
        for quote in driver.find_elements(By.CSS_SELECTOR, ".quote"):
            rows.append({
                "text": quote.find_element(By.CSS_SELECTOR, ".text").text,
                "author": quote.find_element(By.CSS_SELECTOR, ".author").text,
                "tags": ", ".join(t.text for t in quote.find_elements(By.CSS_SELECTOR, ".tag")),
            })
        try:
            next_link = driver.find_element(By.CSS_SELECTOR, "li.next a")
        except NoSuchElementException:
            break                                   # last page
        first_quote = driver.find_element(By.CSS_SELECTOR, ".quote")
        next_link.click()
        wait.until(EC.staleness_of(first_quote))    # wait for the old page to go away
        page += 1
        time.sleep(1)                               # be polite: one page per second
finally:
    driver.quit()

with open("quotes.csv", "w", newline="", encoding="utf-8") as f:
    writer = csv.DictWriter(f, fieldnames=["text", "author", "tags"])
    writer.writeheader()
    writer.writerows(rows)

print(f"Scraped {len(rows)} quotes from {page} pages into quotes.csv")
Scraped 100 quotes from 10 pages into quotes.csvWaiting for the old first quote to become stale after clicking Next is a reliable way to know the new page has replaced the old one, without guessing a delay. The one-second pause between pages is for politeness, not correctness.
Scraping Infinite Scroll
import time
from selenium import webdriver
from selenium.webdriver.common.by import By

options = webdriver.ChromeOptions()
options.add_argument("--headless=new")
driver = webdriver.Chrome(options=options)
try:
    driver.get("https://quotes.toscrape.com/scroll")
    time.sleep(1)
    seen = 0
    while True:
        driver.execute_script("window.scrollTo(0, document.body.scrollHeight);")
        time.sleep(1.5)                               # give the next batch time to load
        count = len(driver.find_elements(By.CSS_SELECTOR, ".quote"))
        print("quotes loaded:", count)
        if count == seen:                             # nothing new appeared: we reached the end
            break
        seen = count
finally:
    driver.quit()
quotes loaded: 20
quotes loaded: 30
...
quotes loaded: 100
quotes loaded: 100The loop scrolls to the bottom, waits for the next batch, and stops when the count stops growing. On real sites, also cap the number of scrolls so a feed that never ends doesn’t run forever.
Selenium + BeautifulSoup
A common pattern is to let Selenium handle loading and interaction, then hand driver.page_source to BeautifulSoup, which is quicker for searching through lots of elements:
from bs4 import BeautifulSoup
from selenium import webdriver

options = webdriver.ChromeOptions()
options.add_argument("--headless=new")
driver = webdriver.Chrome(options=options)
try:
    driver.get("https://books.toscrape.com/catalogue/category/books/travel_2/index.html")
    html = driver.page_source                 # the rendered HTML
finally:
    driver.quit()

# Parse the HTML with BeautifulSoup, which is faster for many lookups
soup = BeautifulSoup(html, "html.parser")
books = []
for card in soup.select("article.product_pod"):
    books.append({
        "title": card.h3.a["title"],
        "price": card.select_one(".price_color").text,
        "rating": card.select_one(".star-rating")["class"][1],   # e.g. "Three"
    })
print(len(books), "books")
for book in books[:3]:
    print(book)
11 books
{'title': "It's Only the Himalayas", 'price': '£45.17', 'rating': 'Two'}
{'title': 'Full Moon over Noah’s Ark: An Odyssey to Mount Ararat and Beyond', 'price': '£49.43', 'rating': 'Four'}
{'title': 'See America: A Celebration of Our National Parks & Treasured Sites', 'price': '£48.87', 'rating': 'Three'}This books site doesn’t actually need JavaScript, so in practice you’d use requests here; the pattern matters when a page needs a click, a login or scrolling before the HTML is complete.
Scraping Responsibly
- Check the site’s terms and robots.txt. Many sites, including large e-commerce sites, forbid automated scraping in their terms. Python’s
urllib.robotparserreads robots.txt for you (it returnedTruefor the books sandbox). - Prefer an official API when one exists; it’s more stable and usually allowed.
- Slow down: add delays between requests and avoid running many browsers in parallel against one site.
- Don’t collect personal data you have no lawful reason to process; data protection laws such as the GDPR apply to scraped data too.
- Expect breakage: selectors change when a site is redesigned, so keep them in one place and fail loudly when nothing is found.
Working around CAPTCHAs, logins you aren’t authorized to use or other anti-bot measures can breach terms of service and, depending on where you are, the law. If a site actively blocks scraping, treat that as a “no”.
Common Selenium Errors
| Error | Usual cause and fix |
|---|---|
NoSuchElementException | The element isn’t there yet or the selector is wrong. Wait with WebDriverWait and check the selector in DevTools with $$('...'). |
StaleElementReferenceException | The page re-rendered after you found the element. Find it again after navigation or updates. |
ElementClickInterceptedException | A cookie banner or overlay covers the element. Close it first, or scroll the element into view. |
TimeoutException | The condition never became true: the content didn’t load, or the selector never matches. |
SessionNotCreatedException | Browser and driver versions don’t match; let Selenium Manager handle the driver instead of a stale copy on your PATH. |
Conclusion
Selenium is the right tool when the data only appears after JavaScript runs or after the user clicks and scrolls. Check first whether plain requests and BeautifulSoup are enough (on the JavaScript version of the quotes site they found 0 quotes, while Selenium found 10), then use explicit waits, a stale-element check for pagination, a “stop when nothing new loads” loop for infinite scroll, and driver.quit() in finally. Above all, scrape only what you’re allowed to, slowly, and prefer an API when there is one. The Selenium WebDriver documentation covers every locator and wait condition.
FAQs
Is Selenium good for web scraping?
Yes, for pages that build their content with JavaScript or need clicks, scrolling or form input. For static pages, requests and BeautifulSoup are much faster and simpler.
Do I still need ChromeDriver or webdriver-manager for Selenium?
No. Since Selenium 4.6, Selenium Manager automatically finds or downloads the correct driver, and can download Chrome for Testing if Chrome is not installed.
How do I wait for an element in Selenium?
Use WebDriverWait with an expected condition, for example WebDriverWait(driver, 10).until(EC.presence_of_element_located((By.CSS_SELECTOR, “.quote”))). Avoid fixed time.sleep calls for waiting on content.
How do I scrape infinite scroll pages with Selenium?
Scroll to the bottom with driver.execute_script(“window.scrollTo(0, document.body.scrollHeight)”), wait briefly, count the items, and stop when the count no longer increases or after a maximum number of scrolls.
Selenium or Playwright for scraping?
Both control real browsers. Playwright has built-in auto-waiting and is often quicker to write; Selenium supports more languages and browsers and has a long track record. Either works for most scraping tasks.
Is web scraping legal?
It depends on the site’s terms, the data and your jurisdiction. Scraping public data politely is often acceptable, but many sites prohibit it in their terms, and personal data is protected by laws such as the GDPR. Prefer official APIs and check before scraping.







